open source · MIT · built with Claude Opus 4.8

Spin up a team of agents.
Ship only the best one.

A multi-team agentic engine for Claude Code. Parallel worker teams generate competing solutions, a consensus gate filters the unstable ones, and an ELO tournament ranks the survivors head-to-head.

The pieces are proven research — AlphaCode, self-consistency, LLM-as-judge, Chatbot-Arena Elo. This packages them into one installable Claude Code skill + engine. Novel as an integration, honest about it.

2 Intelligence · 4 Execution · 1 Judge 50% consensus stability gate ELO head-to-head ranking 86 offline tests passing
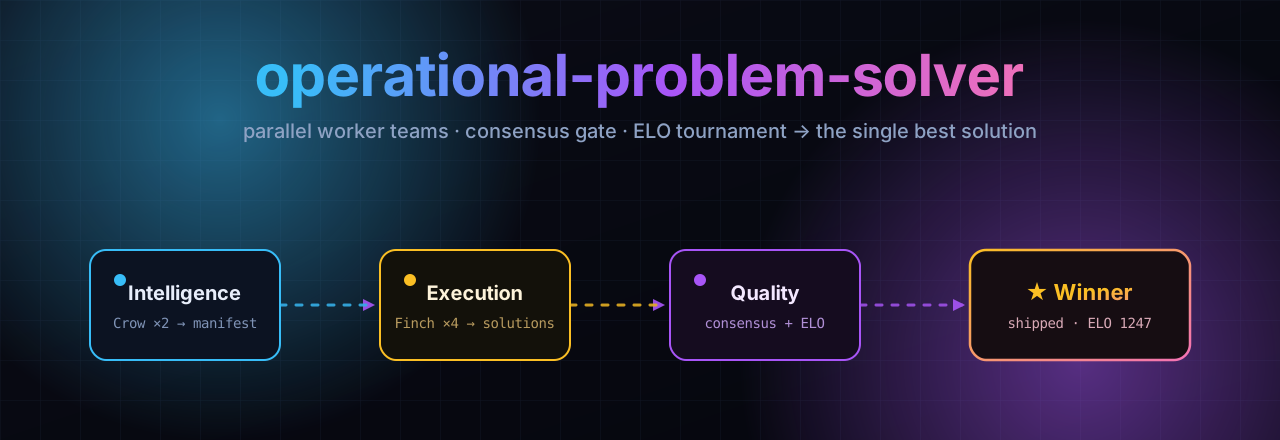
Pipeline: Intelligence to Execution to Quality to Winner
// three worker teams

One orchestrator, three crews.

Each team runs multiple instances in parallel. Workers are isolated so they don't converge on the same idea.

01 — Crow ×2

Intelligence

Reads the directory, detects language, dependencies and constraints, then merges everything into one shared Context Manifest.

→ context manifest
02 — Finch ×4

Execution

Parallel, isolated workers. Same manifest, a different strategy each — simplest, fastest, most robust, cleanest. One standalone solution apiece.

→ N candidate solutions
03 — Consensus + ELO

Quality Assurance

Layer 1 gates on a 50% stability threshold (syntax, lint, optional tests). Layer 2 runs the ELO tournament and ships the winner.

→ ranked leaderboard
// quality assurance · layer 2

The ELO tournament, live.

Survivors are judged pairwise by Opus. Each match updates ELO (K=32, start 1000), blended with objective lint/test scores. Hit run.

idle · 4 competitors, round-robin
// one command

Run it from your shell.

Install the engine, point it at a problem, read the leaderboard. The skill calls this for you inside Claude Code.

ops-solvecopy
$ ops-solve "solve: write a Python is_prime(n) with tests" --workers 4 --test-cmd "pytest -q {file}"

Context Manifest (Intelligence)  language=python · constraints: handle n<2, even numbers
QA Layer 1 — consensus           4/4 stable  (met)

QA Layer 2 — ELO leaderboard
  #  worker      ELO   W-L-D   final
  1  Finch-03   1064   3-0-0   0.94  ★ WINNER
  2  Finch-01   1012   2-1-0   0.71
  3  Finch-04    978   1-2-0   0.55
  4  Finch-02    946   0-3-0   0.38

winner → runs/run-…/WINNER/solution.py     calls: 18
// execution protocol

Phase I → II → III.

If fewer than half the workers produce stable output, the engine mutates the prompts and re-loops Execution before judging.

PHASE I

Audit

Intelligence team probes the environment and builds the shared Context Manifest.

PHASE II

Generate

Execution workers produce diverse standalone solutions in parallel, each isolated.

PHASE III

Judge & ship

Consensus gate → ELO tournament → the highest-rated solution is written out.

⚡

Honest about cost. Every worker and the judge are metered Claude API calls — 18 per run by default (2 intelligence, 4 workers, 6 judge pairs in both orders), and the CLI prints the count before it starts. Prompt caching, a --cheap Haiku tier, and fewer workers keep it down. The engine prints an estimated dollar cost every run. The offline test suite runs the ELO and consensus logic with a mocked model — zero API spend.
✦ Deerflow